 Read Results - [source code]
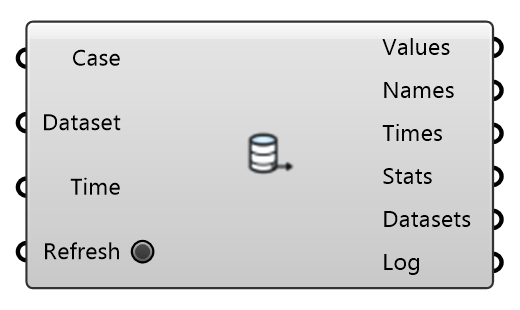
Read what a case's function objects wrote under postProcessing/ — forces, force coefficients, y+, flow rates, volume/surface field values, probe histories, sampled profiles — as columns of numbers, with per-column statistics. One grammar reads every tabular file OpenFOAM writes there, including function objects Eddy3D has never heard of. Restart slices of a time series are stitched with the later run winning; a sampled profile is one snapshot per time.
Input
| Name | Nickname | Description | Type |
|---|---|---|---|
| Case | A written case: a wind study (one sub-result per direction), a loaded study, a UMF case, an indoor case, or a path to a case folder. | Generic Data | |
| Dataset | Which output to read, as function/file (e.g. forces/force.dat, probes/U, air/probes/T for a region-nested UMF case) or just the function name when it writes one file. Leave empty to read the only dataset present; the Datasets output always lists what is available. | Text | |
| Time | For a sampled PROFILE (a file whose first column is distance, not time): which snapshot to read — empty or latest = the latest start time, a number = that start time. Ignored for a time series, whose restart slices are always stitched. | Text | |
| Refresh | Re-read the files now. Momentary. Results are read off the solution thread and cached until the inputs or the files change; a solve still writing to the case needs this to pick up new rows. | Boolean |
Output
| Name | Nickname | Description | Type |
|---|---|---|---|
| Values | The numbers: branch = {sub-result, column}, items = one per row. Column 0 (time or distance) is on the Times output, not here. | Number | |
| Names | Column names in Values order, taken from the file's own header — OpenFOAM's names where it writes them (total_x), component suffixes (U_x) where it does not, probe coordinates folded in. | Text | |
| Times | The independent variable per sub-result: solver time for a series, distance for a profile. | Number | |
| Stats | One line per column: last value, tail mean (final fifth — what a report quotes), min, max, sample count, and for a time series whether it has SETTLED by the KPSS stationarity test over the trailing half, with the two-fifths drift as a reading aid. | Text | |
| Datasets | Every tabular dataset found under postProcessing/, as function/file keys. | Text | |
| Log | What was read, from where, and anything that was dropped, replaced or skipped. | Text |